 QA

Playwright flaky tests can pass and fail intermittently across executions despite identical codebases. These random failures usually originate from test-level design flaws—such as hardcoded timeouts, shared state, sequential test coupling, live API requests, and resource-starved CI environments—rather than browser engine bugs. You can eliminate them by adopting auto-waiting web assertions, cleanly scoped fixtures, mocked network layers, failure trace capture, and automated CI quality gates that flag and fail on flakiness.
Who this is for: QA engineers and SDETs running Playwright Test (TypeScript) in CI. Prerequisites: a working Playwright project and basic async/await. Applies to: Playwright 1.52 and later (latest release: 1.65). Last updated: November 17, 2026.
Playwright flaky tests are the fastest way to lose a team’s trust in automation. The suite goes red, someone clicks re-run, it goes green, and nobody asks why. A few weeks later, real failures get re-run too.
The cost builds quietly: wasted CI minutes, blocked merges, and engineers who stop reading test reports. Retries hide the problem. They don’t fix it.
Across 11+ years of building and maintaining test automation, I’ve found that most flaky Playwright tests trace back to a short list of causes, and each has a specific fix. This guide covers how to detect them, seven root causes with bad and good code, and a CI setup that stops new flakes from merging.

What Are Playwright Flaky Tests?
A flaky test is a test that gives different results on the same code: it passes on one run and fails on another.
Playwright makes this precise. With retries turned on, the runner puts every test into one of three groups (Playwright docs: Retries):
- Passed: passed on the first run.
- Flaky: failed on the first run, then passed on a retry.
- Failed: failed on the first run and on every retry.
The catch is the default. Flaky tests count as successes unless you pass --fail-on-flaky-tests (Playwright CLI docs). A pipeline can stay green while the same five tests flake every day.
That’s why flakiness is a quality problem, not a cosmetic one. A flaky test either hides a real race condition in your app or trains the team to ignore red builds. Both cost more than the test saves.
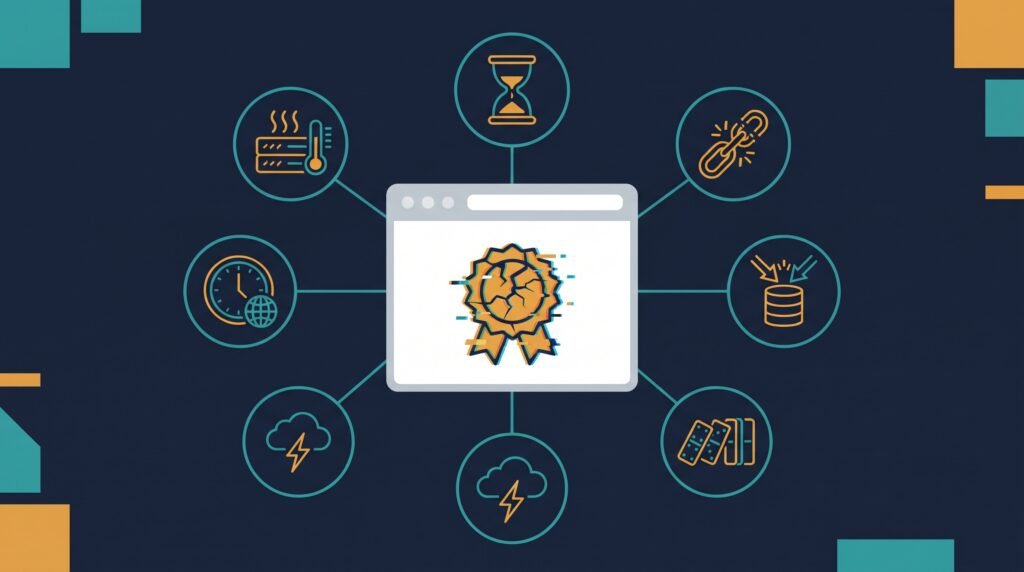
Why Playwright Flaky Tests Happen: 7 Root Causes
Each cause below has the same shape: the bad pattern, why it flakes, and the fix. Once you know them, you can usually spot them in a code review.
1. Hard waits and one-off state checks
waitForTimeout guesses how long the app needs. isVisible() checks once and returns straight away. Both pass on a fast machine and fail on a slow one.
// Bad: a fixed sleep, then a one-off check
await page.getByRole('button', { name: 'Save' }).click();
await page.waitForTimeout(2000);
expect(await page.locator('.toast').isVisible()).toBe(true);
// Good: a web-first assertion retries until it passes or times out
await page.getByRole('button', { name: 'Save' }).click();
await expect(page.getByRole('status')).toHaveText('Saved');Web-first assertions such as toBeVisible() and toHaveText() re-check the page until the condition holds (Playwright docs: Best practices).
2. Brittle locators
Long CSS chains and nth-child selectors break when a list renders in a different order or a wrapper div changes. They can also match two elements during a re-render, which triggers a strict-mode error only some of the time.
// Bad: tied to DOM structure
await page.locator('div.list > div:nth-child(3) button').click();
// Good: tied to what the user sees
await page
.getByRole('listitem')
.filter({ hasText: 'Invoice #1042' })
.getByRole('button', { name: 'Pay' })
.click();3. Shared test data
Two parallel workers editing the same user, cart or record will overwrite each other. The test passes alone and fails in a full run.
// Bad: every test edits the same account
await page.getByLabel('Email').fill('qa-user@example.com');
// Good: unique data per test
const email = `qa-${test.info().workerIndex}-${Date.now()}@example.com`;
await page.getByLabel('Email').fill(email);4. Order-dependent tests
Test B relies on something test A created. That works in serial mode, then breaks under fullyParallel, sharding or a retry, because a retry starts a fresh worker and test A doesn’t run again (Playwright docs: Retries).
The fix is a rule, not a snippet: every test creates the state it needs, through an API call or a fixture, and never reads state another test left behind.
5. Unmocked network and third-party calls
A slow staging API, a rate-limited payment sandbox or a third-party chat widget adds timing you don’t control. Assertions written for the happy path fail when the response is slow or comes back empty.
// Good: start waiting for the response before you trigger it
const orderResponse = page.waitForResponse(
  (res) => res.url().includes('/api/orders') && res.ok()
);
await page.getByRole('button', { name: 'Place order' }).click();
await orderResponse;
// Good: stub a third-party script you don't own
await page.route('**/widget.thirdparty.com/**', (route) =>
route.fulfill({ status: 200, body: '' })
);6. Time, time zones and animations
Tests that read “today”, depend on the runner’s time zone or click mid-animation will pass at 10 a.m. and fail at midnight UTC.
// Good: freeze the clock for date-dependent UI
await page.clock.setFixedTime(new Date('2026-01-15T10:00:00'));
await page.goto('/billing');
await expect(page.getByText('Due in 14 days')).toBeVisible();
Set timezoneId and locale in the config so CI and laptops render the same dates (Playwright docs: Emulation).
7. Starved CI runners
The same suite that passes on an 8-core laptop can time out on a 2-vCPU runner running four workers. Timing-sensitive tests are the first to break.
Match workers to the runner’s cores, and split large suites across machines with --shard instead of piling more workers onto one runner (Playwright docs: Sharding).
How to Fix Playwright Flaky Tests: Step-by-Step
Fixing flakiness is a loop: reproduce it, record evidence, fix the cause, then gate CI so it can’t come back. The six steps below follow that order.
Step 1: Reproduce the flake on demand
You can’t fix what you can’t reproduce. Run the suspect file many times with retries off and more workers than usual, so timing problems show up.
npx playwright test tests/checkout.spec.ts --repeat-each=20 --retries=0 --workers=4If it only fails under load, the cause is usually shared data (cause 3) or starved resources (cause 7). If it fails with --workers=1 too, look at waits, locators and time (causes 1, 2 and 6).
Step 2: Set a flake-resistant baseline config
This config retries once in CI, records a trace on that retry, and fails the run if any test needed the retry to pass.
// playwright.config.ts
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  fullyParallel: true,
  forbidOnly: !!process.env.CI,
  retries: process.env.CI ? 1 : 0,
  failOnFlakyTests: !!process.env.CI,
  workers: process.env.CI ? 2 : undefined,
  reporter: [['html', { open: 'never' }], ['list']],
  use: {
    baseURL: process.env.BASE_URL ?? 'http://localhost:3000',
    trace: 'on-first-retry',
    screenshot: 'only-on-failure',
    timezoneId: 'UTC',
    locale: 'en-US',
    contextOptions: { reducedMotion: 'reduce' },
  },
  projects: [{ name: 'chromium', use: { ...devices['Desktop Chrome'] } }],
});
failOnFlakyTests needs Playwright 1.52 or later (Playwright docs: TestConfig). Start with workers: 2 and tune it to your runner’s cores.

Step 3: Read the trace, not the error message
The error tells you where a test failed. The trace tells you why: the DOM snapshot before and after each action, network calls, console logs and timing.
npx playwright show-report
# or open one trace directly
npx playwright show-trace test-results/<test-folder>/trace.zip
Check three things in order: what the DOM looked like at the failed step, which network calls were still pending, and whether an earlier action landed on the wrong element (Playwright docs: Trace viewer).
Step 4: Isolate test data with fixtures
Give every test its own data through a fixture that creates it before the test and cleans it up after. Swap /api/test-users for your app’s own seeding endpoint.
// tests/fixtures.ts
import { test as base, expect } from '@playwright/test';

type Account = { email: string; password: string };

export const test = base.extend<{ account: Account }>({
  account: async ({ request }, use, testInfo) => {
    const email = `qa-${testInfo.workerIndex}-${Date.now()}@example.com`;
    const password = 'Test#12345';

    const res = await request.post('/api/test-users', { data: { email, password } });
    expect(res.ok()).toBeTruthy();

    await use({ email, password });

    await request.delete(`/api/test-users/${encodeURIComponent(email)}`);
  },
});

export { expect };
Tests import test from this file and ask for account. No two tests ever share a user, so fullyParallel and sharding stay safe (Playwright docs: Fixtures).
Step 5: Wait for conditions, never for time
Use a web-first assertion for anything on the page. For things off the page, such as a background job or an email, poll the condition with expect.poll.
// Wait for a background job, not a fixed 10 seconds
await expect
  .poll(async () => {
    const res = await request.get('/api/jobs/42');
    return (await res.json()).status;
  }, { timeout: 30_000 })
  .toBe('done');
Step 6: Quarantine, then gate CI
A test you can’t fix today shouldn’t block every merge, but it can’t disappear either. Tag it, run it in a separate non-blocking job, and open a ticket.
test('applies discount at checkout', { tag: '@quarantine' }, async ({ page }) => {
  // known flaky: tracked in QA-1234
});
# .github/workflows/e2e.yml (blocking job)
- run: npx playwright test --grep-invert @quarantine --shard=${{ matrix.shard }}/4If you’re setting up the matrix itself, my guide to the GitHub Actions multi-browser matrix walks through the full workflow file.
Retries vs Quarantine vs Rewrite: Which One When?
Teams usually reach for retries first because they’re one line of config. The table shows why retries should be the safety net, with a rewrite as the actual fix.
| Criterion | Retries | Quarantine | Rewrite the test |
|---|---|---|---|
| What it does | Re-runs a failed test automatically | Moves the test to a non-blocking job | Removes the root cause |
| Fixes the cause | No | No | Yes |
| Keeps CI green | Yes, but can hide real bugs | Yes, honestly | Yes |
| Effort | Minutes | Minutes, plus a ticket | Hours to days |
| Risk | Real race conditions ship unnoticed | The test is forgotten and coverage drops | Low |
| Use it when | A genuinely external blip, such as a browser crash | A known flake you can’t fix this sprint | Always the end goal |
| Playwright feature | retries + failOnFlakyTests | Test tags + --grep-invert | Web-first assertions, fixtures, page.route |
The rule I follow: retries tell you that a test is flaky, quarantine buys you time, and only a rewrite closes the ticket.
Edge Cases and Production Pitfalls
These flakes survive the basic fixes because they hide in setup, rendering or the browser itself. Each one comes with the symptom to look for.
- Clicking before hydration. The button is visible, but the framework hasn’t attached its handler yet, so the click does nothing. Symptom: the next assertion times out, and the trace shows the click “succeeded”. Fix: wait for a signal that only appears after hydration, such as an element rendered client-side or a
data-readyattribute. beforeAllside effects plus retries. A retry starts a new worker and runsbeforeAllagain, creating duplicate records. Symptom: “already exists” errors only on retries. Fix: make setup idempotent, or move it into per-test fixtures.- Expired auth state. A
storageStatefile saved hours earlier holds tokens that expire mid-run. Symptom: random redirects to the login page late in long suites. Fix: regenerate auth in a setup project on every run (Playwright docs: Authentication). - Service workers bypassing
page.route. Requests handled by a service worker never reach your route handler. Symptom: the mock is ignored only on PWA pages. Fix: setserviceWorkers: 'block'inusefor those tests. - Screenshot diffs across operating systems. Fonts and anti-aliasing render differently on macOS and Linux. Symptom: visual tests pass locally and fail in CI by a few pixels. Fix: generate baselines inside the same Docker image CI uses; see Docker for QA: containerizing browsers.
- Over-wrapping with
toPass. Wrapping clicks and form submits in a retry block can submit twice and hide real bugs. Symptom: duplicate orders in test data. Fix: retry only read-only checks, and keep actions outside the block. - Timeouts that fight each other. An expect timeout longer than the test timeout means the assertion never gets its full window. Fix: keep
expect.timeoutwell below the testtimeout, and raise them per test only when a slow flow needs it.

Conquering Flaky Tests in Playwright
Flaky tests drain team productivity and mask real regressions in your CI/CD pipeline. Dive into the root causes of test instability—from hard waits and brittle locators to asynchronous race conditions—and discover actionable strategies to achieve 100% test reliability with Playwright.
Playwright Flaky Tests Checklist
Use this in code review. If a new test fails any item, fix it before it merges.
- No
waitForTimeout, and noisVisible()ortextContent()insideexpect(...). Use web-first assertions. - Locators use roles, labels or test IDs, never
nth-childor long CSS chains. - Every test creates its own data through a fixture or API call, with unique values per worker.
- No test depends on another test’s state or run order.
- Third-party scripts are stubbed with
page.route, and response waits start before the action that triggers them. - Clock,
timezoneIdandlocaleare fixed for any date-dependent assertion. - CI uses
retries: 1,trace: 'on-first-retry'andfailOnFlakyTests. - Workers match runner cores; big suites are sharded.
- Every quarantined test has a tag, a ticket and an owner.
- New tests pass
--repeat-each=20 --retries=0locally before review.
Internal Blog Links
- Testcontainers in Python: 7 Best Database Secrets
- Docker Compose for Multi-Service Mocks: 7 Best Secrets
- Docker for QA: 7 Best Test Container Secrets
- Stable Automated Tests: A Powerful Guide to UI, API & Integration
- Microservices Testing Strategy: Unit vs Integration vs E2E Balance
- Designing a Clean Enterprise Test Automation Framework from Scratch
Internal Series Links
- Learn Python – Zero to Hero
- Playwright Forge — Modern Web Automation
- Agentic QA & LLMs — AI Driven Quality Engineering
- API & Performance Testing
- Enterprise SDET Architect — Frameworks, CI/CD & Leadership
- LangGraph: Complete Zero to Hero
- Claude Code Tutorial: Complete Zero to Hero
- Learn MCP – Zero to Hero
- Cursor AI: Complete Zero to Hero
- OpenAI Codex: Complete Zero to Hero
- AutoGen: Complete Zero to Hero Guide
- AI Agents for QA: Zero to Hero
- Python for Data Science: Complete Zero to Hero
- Learn Playwright – Zero to Hero
- Learn Cypress Testing – Zero to Hero
- Learn Selenium WebDriver – Zero to Hero
- Postman AI: Complete Zero to Hero
- XCUITest iOS Testing: Complete Zero to Hero
- Appium: Complete Zero to Hero
- Detox React Native Testing: Complete Zero to Hero
- EarlGrey: Complete Zero to Hero
- Espresso Android Testing: Complete Zero to Hero
- Flutter Integration Testing: Complete Zero to Hero
- Maestro Mobile Testing: Complete Zero to Hero
- Robot Framework Appium: Complete Zero to Hero
- UI Automator: Complete Zero to Hero
- WebdriverIO Mobile: Complete Zero to Hero
- SQL Mastery: From Basics to Advanced
- TencentDB Agent Memory: Complete Zero to Hero
- DataRobot: Complete Zero to Hero
- Deepnote AI: Complete Zero to Hero
- Jupyter AI: Complete Zero to Hero
- AWS Q Developer: Complete Zero to Hero
- Azure AI DevOps: Complete Zero to Hero
- Docker AI: Complete Zero to Hero
- GitHub Actions AI: Complete Zero to Hero
- Google Cloud AI: Complete Zero to Hero
- Kubernetes AI: Complete Zero to Hero
- Terraform AI: Complete Zero to Hero
- Free QA Resources Built From Real Experience
- QA Glossary: Test Automation Terms Every Engineer Should Know
People Asked Questions
Why are my Playwright tests flaky in CI but not locally?
CI runners usually have fewer CPU cores, run more workers per core, use a different OS and time zone, and start from empty data. Timing-sensitive tests break first. Match workers to cores, fix the time zone and locale in config, and generate visual baselines in the same Docker image CI uses.
How many retries should I set in Playwright?
Use zero retries locally so you see flakes straight away, and one retry in CI so a single external blip doesn’t block merges. Pair that retry with trace: 'on-first-retry' for evidence and failOnFlakyTests so a pass-on-retry still fails the build until someone fixes it.
How do I find flaky tests in Playwright?
Turn on retries and check the HTML report for tests labelled “flaky”. To reproduce one, run it with --repeat-each=20 --retries=0 and more workers than usual. A test that fails even once in twenty runs is flaky and needs a fix, not a retry.
Does Playwright wait for elements automatically?
Yes. Before an action like click(), Playwright checks that the element is visible, stable, enabled and able to receive events. Web-first assertions such as toBeVisible() also retry until they pass. Manual checks like isVisible() don’t wait, which is why they cause flakes (Playwright docs: Actionability).
Is waitForTimeout ever okay in Playwright tests?
Only while debugging locally. In committed tests, a fixed sleep is either too short on a slow runner, which causes flakes, or too long everywhere else, which wastes CI time. Replace it with a web-first assertion, waitForResponse, or expect.poll for conditions off the page.
Conclusion
Playwright flaky tests are rarely Playwright’s fault. They come from timing guesses, shared data, order dependence, live dependencies, unfixed clocks and overloaded runners. Each one has a concrete fix, and the tools are already built in.
Start small. Add the baseline config, turn on failOnFlakyTests in CI, and run --repeat-each on your three most-retried tests this week. Once the suite stops crying wolf, people start trusting red builds again.
New to Playwright? Start with Learn Playwright: Zero to Hero. For stability across UI, API and integration layers, read Stable Automated Tests: UI, API and Integration. If your team needs hands-on help taming a flaky suite, see automation testing services.